Laravel Forge, Vapor, Cloud, and Envoyer: which problem each one solves

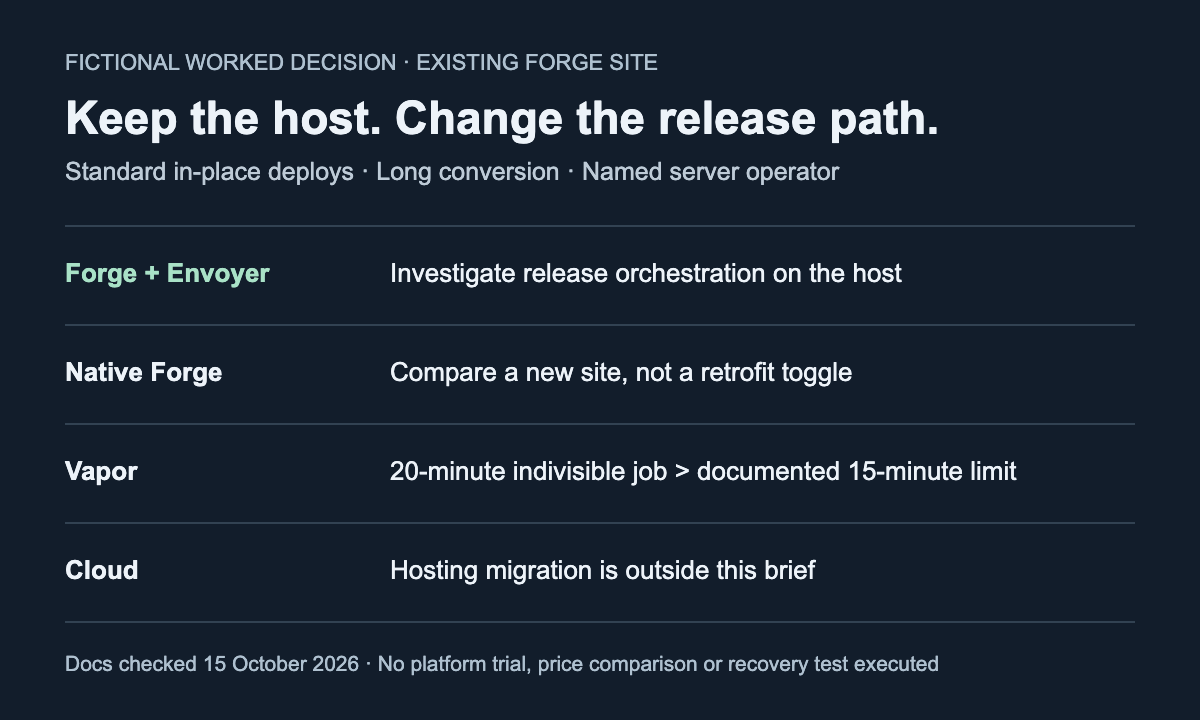
A worked release decision separates Forge and Envoyer from an infrastructure move to Vapor or Cloud, with current worker and deployment constraints.
Decide whether you are changing releases or hosting
Consider a fictional team operating a Laravel application on an Ubuntu server managed through Forge. Its existing site uses standard, in-place deployments. It has a named server operator, private uploads and a queued conversion that must be allowed to run for twenty minutes without splitting it. The immediate goal is to prepare a release before switching web traffic to it, while retaining the host. The team can change its deployment directory layout but cannot move infrastructure this quarter. This is a worked decision brief, not an Ulties production account.
I recommend investigating Forge with Envoyer first for that brief. The problem is release orchestration on an existing host, rather than a missing place to run PHP. A new Forge site with native zero-downtime deployments is an alternative worth pricing and rehearsing. Vapor would require a change to the long job. Cloud would change the infrastructure arrangement. None of these options has been deployed or costed for this article.
Forge already has a release-directory option
Forge manages servers and application deployments, including queue workers and scheduled jobs. Its current deployment documentation describes native zero-downtime releases: prepare a new directory and activate it using a symbolic link. Standard deployments instead update the existing directory in place. Forge is therefore not simply “servers without release orchestration.”
There is an important constraint for the fictional existing site: Forge says native zero-downtime deployments must be selected when creating a new site and cannot be added later to an existing one. Its documentation also warns against combining that strategy with Octane. Our example assumes ordinary PHP-FPM, not Octane. Recreating the site with the appropriate strategy would be a migration to rehearse, not an imaginary toggle on the old site.
I recommend an explicit Forge ownership split: the platform automates supported server and site tasks. The team owns application capacity decisions, storage placement, restore verification and the response to an unhealthy job. A release directory is not a backup. Sharing uploads across releases also does not protect them from loss of the host.
Envoyer changes deployment, not the host underneath it
Envoyer deploys to existing servers. Its documented lifecycle includes preparing a release, switching the current symlink and purging old releases. Custom hooks can run around fixed deployment steps. A non-zero hook exit cancels the deployment. Forge documents importing a Forge server and site into an Envoyer project. This is a deployment arrangement layered onto infrastructure, not a replacement database or worker host.
For the example, I would rehearse an Envoyer layout with persistent uploads outside disposable release directories, then configure the links and permissions explicitly. Envoyer’s upload guidance describes storage beside current and linked folders. That is not permission to put private uploads behind a public symlink. The application still needs to authorize downloads, and an operator must prove that an uploaded file survives activation and pruning of an old release.
Envoyer’s configured HTTP health check expects a 2xx response after deployment. That can establish that the selected endpoint answered, not that a conversion finished or a restore works. My proposed release gate includes a separate synthetic conversion and private-download check. A green health URL alone would not approve the fictional migration.
Vapor needs a different plan for the indivisible job
Vapor’s current queue documentation describes its AWS SQS-backed path and a fifteen-minute maximum for a queued job. A fictional twenty-minute indivisible conversion does not fit that documented path. Increasing queue visibility time controls when delivery becomes eligible again; it does not extend the execution allowance. This is a statement about Vapor’s documented model, not a blanket limit on every AWS Lambda product.
I would prefer to reopen Vapor if the work can be split into restartable stages, or if the long operation moves to another service with a documented completion protocol. That introduces an application design and another operational boundary to evaluate. More invocations do not make one indivisible operation shorter, and repeated delivery still needs safe application behavior. No Lambda function, SQS queue or alternative worker was provisioned here.
Cloud is an infrastructure decision, with explicit worker behavior
Laravel Cloud supports worker clusters and custom long-lived background processes. Its docs say configured processes run on every cluster instance and that Laravel queue workers restart after deployment. A worker that follows an App cluster can stop when the App cluster sleeps even if background work is running. For work that must not be interrupted, the documentation directs you to keep the worker cluster awake.
Current Cloud guidance also deprecates queue clusters and gives 30 September 2026 as their sunset date. A new design should use the documented managed-queue or worker-cluster model rather than copying an old queue-cluster walkthrough. This comparison considers an awake worker cluster; it does not establish that every Cloud queue option has identical limits or behavior.
I would evaluate Cloud when the team is allowed to hand over infrastructure operation, then verify runtime dependencies, database connectivity and the selected worker behavior with the actual workload. That may be worthwhile, but it does not meet this quarter’s fictional keep-the-host constraint. No region, resource size, migration duration or savings estimate is asserted.
Walk through the release failure before approving the change
Suppose release B adds a nullable conversion metadata field while a worker running release A is still processing a job. Activating B changes the web code selected for new requests; it does not demonstrate that A’s in-flight work understands a new message shape or schema requirement. My proposed sequence is to keep the first migration additive, preserve the old message contract, and verify both application versions against the intermediate schema before making a later field mandatory.
If B fails its functional check after writing new-format data, switching the web symlink back to A is only a code rollback. It does not undo the database writes, revoke generated links or remove published files. I recommend preserving the failed job record and establishing its outcome before replay. The operator also needs a deliberate worker drain or restart procedure and a verified restore path. None was exercised for this article.
The conditional decision is to fund the Forge-plus-Envoyer rehearsal first, compare it with a new native-release Forge site, and retain the server operator’s responsibilities. I would reverse that recommendation if infrastructure relocation becomes acceptable or the long job becomes safely divisible. Current capabilities were checked on 15 October 2026. The comparison supplies a shortlist and failure analysis, not platform test results or a claim that one product is cheapest.