PHP vs Node vs Rails for modern product teams

A worked stack decision for an account export: compare Laravel, Fastify and Rails against worker recovery, download permissions and operational ownership.
Choose a system the team can operate
PHP is a language, Node.js is a runtime, and Rails is an application framework. I recommend comparing named application stacks against a product workflow rather than treating those labels as interchangeable alternatives. Here the workflow is an account member requesting a CSV export, leaving the page, and returning to download it.
Consider a fictional team that already runs Laravel services backed by PostgreSQL and uses private S3 storage, but has no production Ruby service or Redis queue. Its TypeScript experience is in the browser. These are stipulated assumptions, not facts about Ulties or a customer. The requirement is to deny new download requests after membership is removed and recover an interrupted export without exposing a partial result.
Name the candidates before comparing them
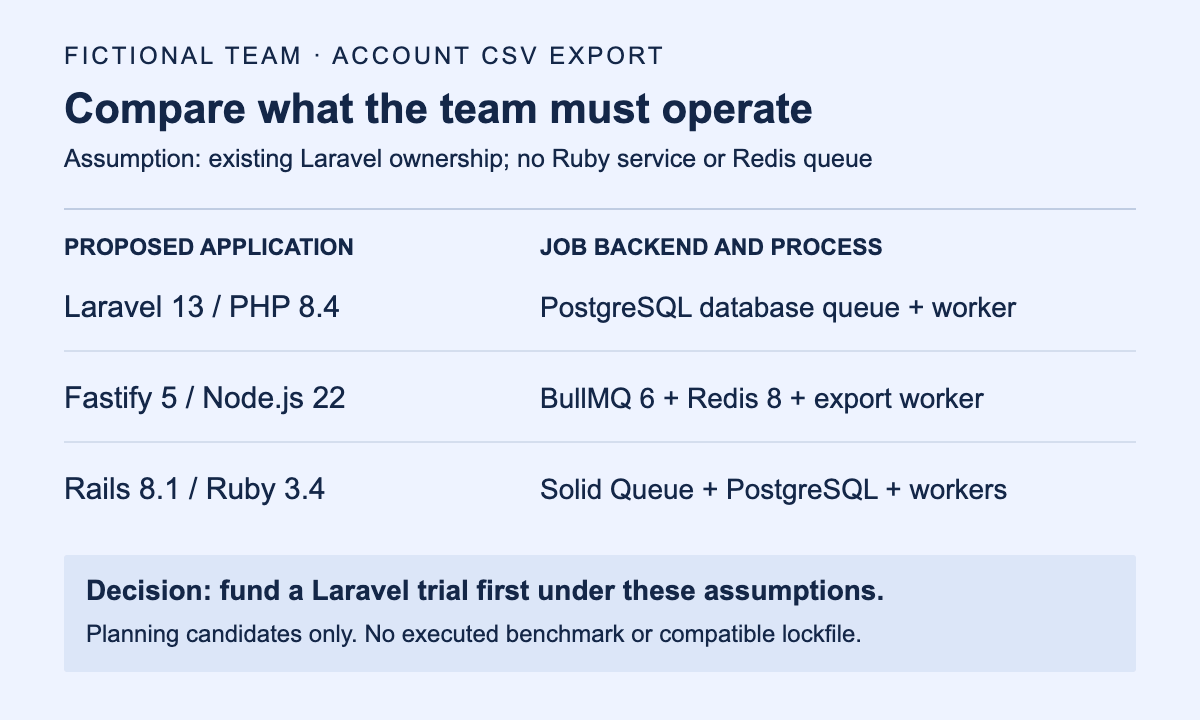
The Laravel proposal is PHP 8.4 with Laravel 13, Eloquent, PostgreSQL 16 and Laravel’s database queue driver, with a separately supervised queue worker. It extends the fictional team’s existing application and account permissions. A database queue is a chosen backend here, not a claim that Laravel requires it.
The Node proposal is Node.js 22 with Fastify 5, node-postgres 8 for database access, BullMQ 6 with Redis 8, and a separate export worker. It uses the same PostgreSQL 16 business data and private S3 storage. Authentication integration, account policy and migrations still need an explicit design; choosing Fastify does not select them for the team.
The Rails proposal is Ruby 3.4 with Rails 8.1, Active Record, PostgreSQL 16 and Active Job using Solid Queue, with its worker processes deployed separately. The same private storage and existing identity-provider integration remain requirements. This proposal does not require introducing Redis.
These release families identify planning candidates as of 15 October 2026. They are not tested compatible lockfiles or a security certification. Before a trial, I recommend recording exact package patches, runtime images and backend configuration, checking their current support status and compatibility, and assigning responsibility for upgrades. Current releases can change that selection.
Compare the worker models, not just the web routes
Laravel’s queue documentation distinguishes database and other queue backends from the synchronous driver that executes immediately. Its queue workers are long-lived: they retain booted application state and need restarting during deployment. Conventional PHP web-request handling therefore does not establish that export workers reset their state between jobs.
Rails 8.1 documents Solid Queue as a database-backed Active Job backend, with queue processes to start and supervise. Its default setup uses a separate queue database. Sharing a database technology does not by itself make a business write and job enqueue one atomic operation. I recommend checking the actual connection and transaction boundary for either database-backed proposal.
Node’s event loop executes JavaScript callbacks; a long synchronous CSV encoding loop can prevent other callbacks in that process from running. Moving the export out of the web process addresses one boundary. BullMQ also documents stalled-job recovery when a worker stops renewing its active-job lock, including when its event loop is too busy. A separate queue worker still needs a design for its own CPU work and lock renewal.
For this workflow, I recommend comparing what an operator must deploy and recover. The Laravel proposal adds a worker to a system the fictional team already knows. The Node proposal also introduces Redis and BullMQ operations for this team. Rails can avoid that Redis dependency, but it still introduces a Ruby application and queue lifecycle. None of those statements predicts measured delivery time or throughput.
Resolve the output and download boundaries
I recommend an export record scoped to an account and an agreed request identity, with its selected data version recorded. The worker must also filter records by that account: protecting a download cannot correct a file assembled from another account’s data. Suppose a worker uploads the CSV and dies before recording completion. A retry must reconcile that output before publishing another result. A stable object key alone is insufficient if a retry reads changed business data and overwrites a different result. The design needs an explicit snapshot or freshness rule and protection against competing attempts publishing completion.
For download authorization, I recommend an application endpoint that checks current membership on each new request and streams from private storage without handing out a reusable storage URL. AWS documents S3 presigned URLs as bearer access that can be reused while valid. If the service instead redirects to such a URL, deleting a membership in the application database does not itself invalidate that issued capability. Its expiry and any credential or policy restrictions remain relevant.
This proposed boundary concerns new requests. It does not erase a file someone already downloaded or necessarily terminate an existing stream. The product owner must decide whether that matches the actual revocation requirement. If short-lived direct links are acceptable instead, I would record that weaker requirement rather than claiming immediate application-level revocation.
Work through the decision
Given the fictional team’s existing Laravel ownership and the absence of a requirement that demands another runtime, I recommend evaluating the Laravel proposal first. This is a decision about which bounded trial to fund, not approval to release an export service. It avoids adding a new language service or Redis queue before there is evidence that either is needed.
I would reopen the choice if the assumptions change. A team already operating Fastify and BullMQ may prefer that proposal. An established Rails team may prefer Active Job and Solid Queue. A measured workload or integration constraint may justify a new runtime. Browser TypeScript familiarity alone does not demonstrate that a team can operate Node queue workers.
For the first trial, I recommend that the backend owner demonstrate an export through the actual configured worker, interrupt it at the upload/completion boundary, and inspect the retry result. The authorization owner should remove membership and attempt a new download. Operations should restart the worker during a deployment and diagnose a failed export from its recorded status. The product owner should agree acceptable completion time before any timing result is judged.
If the trial fails, I recommend first identifying the failing boundary. A presigned-link policy mismatch is not evidence that the language is wrong. An unhandled retry is not proof that another queue library would make the export idempotent. A different stack becomes a stronger candidate when it addresses the identified constraint and the team can own the resulting system.
Keep the evidence boundary visible
No equivalent applications were built or timed for this comparison, and no worker interruption or S3 authorization test was executed here. Framework documentation establishes the mechanisms described, not this export’s correctness. The fictional decision does not establish hiring availability, productivity, security or cost savings. The proposed trial still needs exact versions and recorded outcomes before a delivery commitment.