The technical debt clients should actually care about

Prioritize technical debt using demonstrated operational cost, data risk, and blocked changes, then define a repair small enough to verify.
Translate the code concern into a consequence
“The integration layer needs refactoring” does not tell a client what to approve. “An interrupted import can create duplicate customer records” gives the team a failure to investigate. I recommend asking for a reproduction before approving a broad rewrite. The demonstration below uses invented records. It is not a diagnosis of an Ulties customer’s system.
I recommend distinguishing a recurring cost of changing a system from an immediate defect or an unpopular coding style. Those may need different responses. A duplication bug needs a correctness fix even if nobody calls it debt. An awkward module name needs a stronger justification if it is neither causing mistakes nor blocking planned work.
Look at what a retry actually does
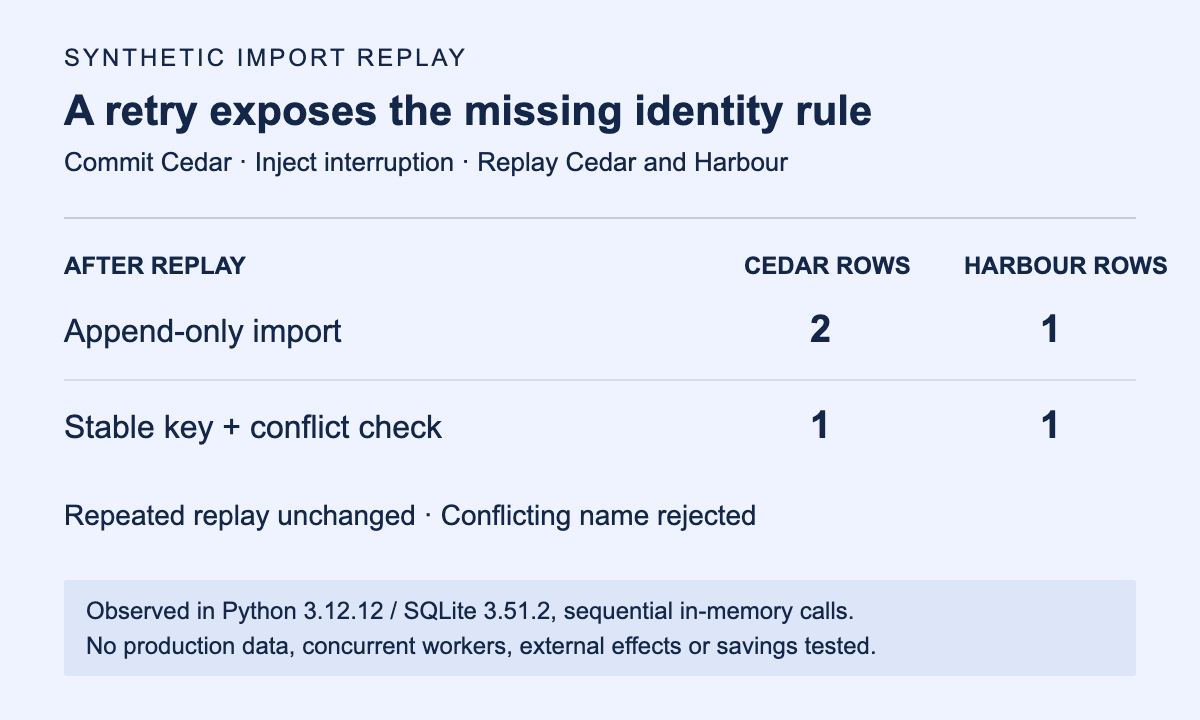
The tested example imports synthetic Cedar and Harbour records into an in-memory SQLite database. Each row has an external identifier. The importer commits Cedar, then raises a deliberate exception before Harbour is written. Retrying the complete input against the append-only version leaves two Cedar rows and one Harbour row. There are three physical rows for two intended customer identities.
The alternative gives the external identifier a primary-key constraint. Repeating that identifier does not insert another row. After the same interruption and replay, Cedar and Harbour each have one row. Replaying again leaves the result unchanged. The fixture ran in an immutable Python 3.12.12 container with SQLite 3.51.2. It is a small behavior test, not a throughput benchmark.
The source-and-test bundle below includes the reproduction helper. Assertions check the committed partial state, both replay results and a repeated replay. Three deliberately changed programs must fail: one overwrites a conflicting name, one omits the conflict check, and one skips the interruption. These controls show that the checks detect those defects; they do not prove that every importer is safe.
Define the repair without promising a new platform
The constraint only works if the identifier represents the intended logical record. For a real integration, I recommend confirming who assigns the identifier, whether it can be reused, and whether it is unique across all sources. Several source systems may need a source-and-identifier key. A customer name or an email address is not automatically a stable identity rule.
This fixture treats a repeated identifier with a different name as a conflict. It rejects the input and retains the original name instead of silently hiding the difference. That is a deliberately narrow policy for this demonstration. A real name change may be valid; agreeing update and version rules is separate work, not something solved by ignoring every duplicate.
Python’s connection context manager commits or rolls back an open transaction when its block ends. The fixture explicitly sets autocommit to false and places the injected exception after the first row’s transaction has committed. The earlier commit therefore remains. SQLite’s ON CONFLICT clause can skip an insert that violates the named uniqueness constraint; it does not repair old duplicates or decide which conflicting business value is correct.
I recommend scoping an initial repair proposal to one import type, its identity rule and its retry cases. Keep historical reconciliation separate. Before adding a uniqueness constraint to a populated database, the team needs an inventory of existing collisions and a reviewed migration and recovery plan. This article authorizes no production data changes.
Compare it with the work you would defer
Suppose a fictional team has this retry defect and a proposal to rename internal modules. Assume the naming change has no known defect or blocked feature attached to it. I recommend investigating the retry boundary because the reproduction shows a correctness failure. I recommend asking the naming proposal to identify a concrete change it would enable before giving it the same priority.
That is an illustrative choice, not a universal ranking or an estimate of financial harm. This toy database does not establish exposure in a live service. Ask whether the real importer follows the same write pattern, whether retries occur, and what downstream work consumes the records. A live security or availability incident may take priority over either proposal.
Google’s SRE guidance describes toil as production-service work that tends to be manual, repetitive and automatable, with no enduring value and growth as the service grows. I recommend using that lens when examining repeated reconciliation. It does not establish that this fictional importer creates support work, or that automating a rare correction will repay its maintenance cost.
State what remains unproved
The demonstration uses sequential calls and a fresh in-memory database. It does not test concurrent workers, process termination, disk durability, a real customer feed or authorization. Its fixed payloads are known-valid inputs. It sends no invoices or other external effects, so it cannot show that replaying those effects is safe. It also does not remove a single historical duplicate.
I recommend approving the smallest real-system investigation that can confirm or reject this diagnosis, followed by a separately bounded repair. Request evidence of the agreed retry and conflict behavior, and a separate review of any data cleanup. If reduced reconciliation is part of the business case, measure that workflow before and after using a consistent definition. No saved hours or customer results were measured here.
Reproduce the examples
Download the executed Python/SQLite demonstration, bounded Docker runner, assertions and three deliberate failure checks. From the extracted root run python3 frontend/content-quality/evidence/import-retry/check.py with Docker available. No production system or savings are tested.
Download the source and tests (.zip)